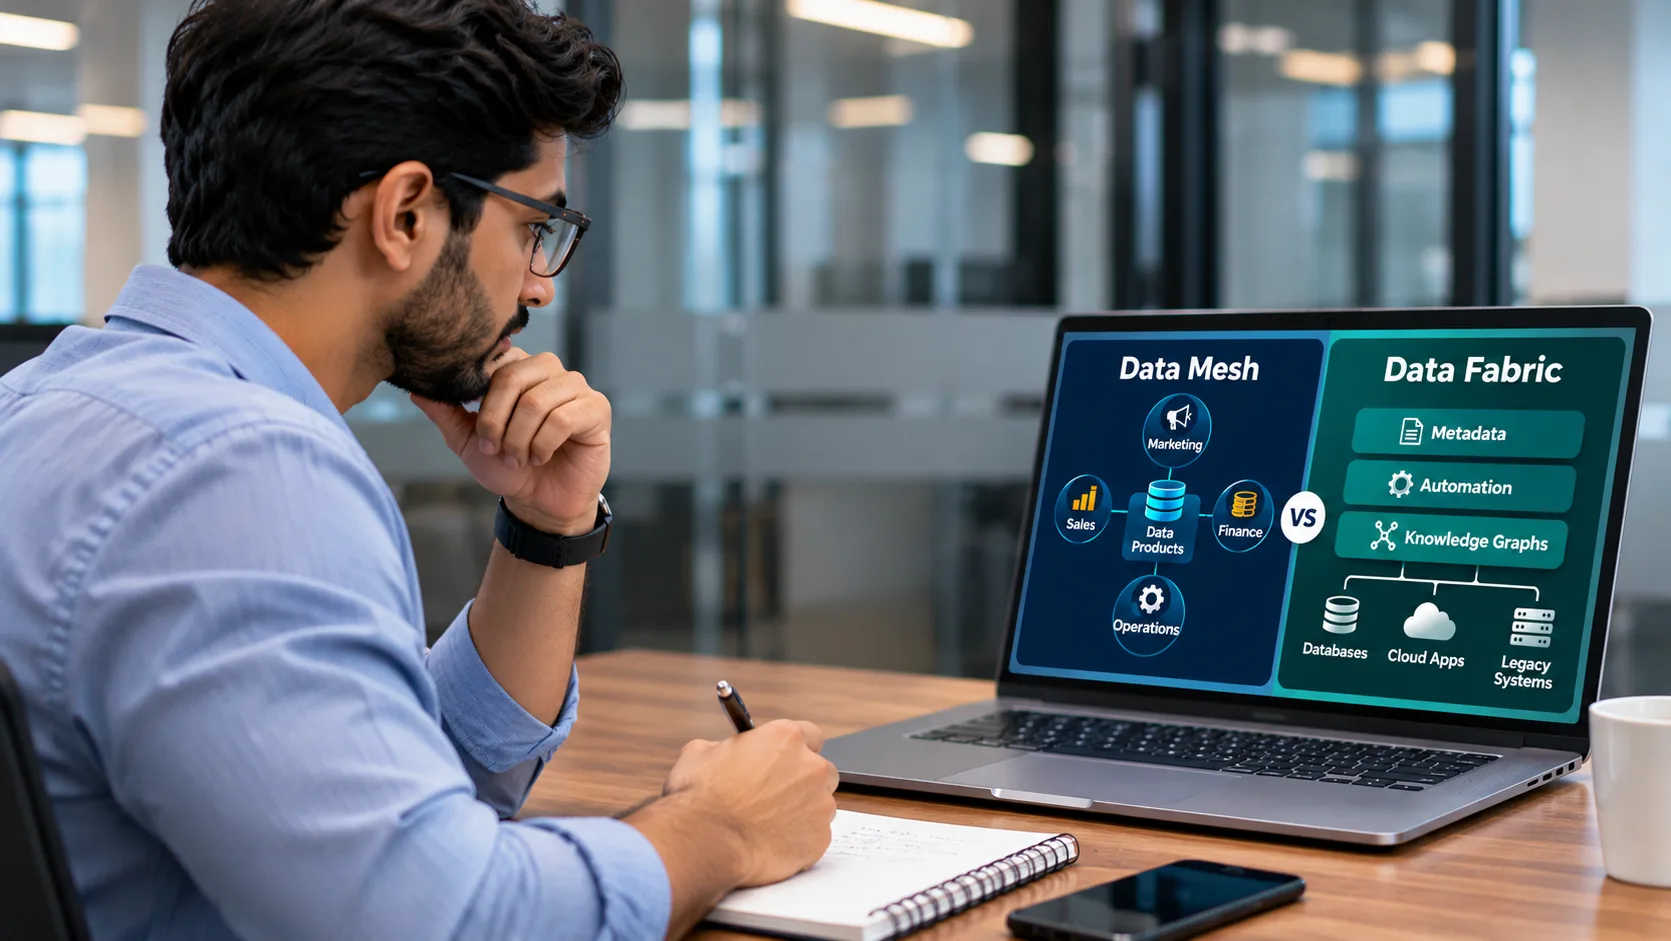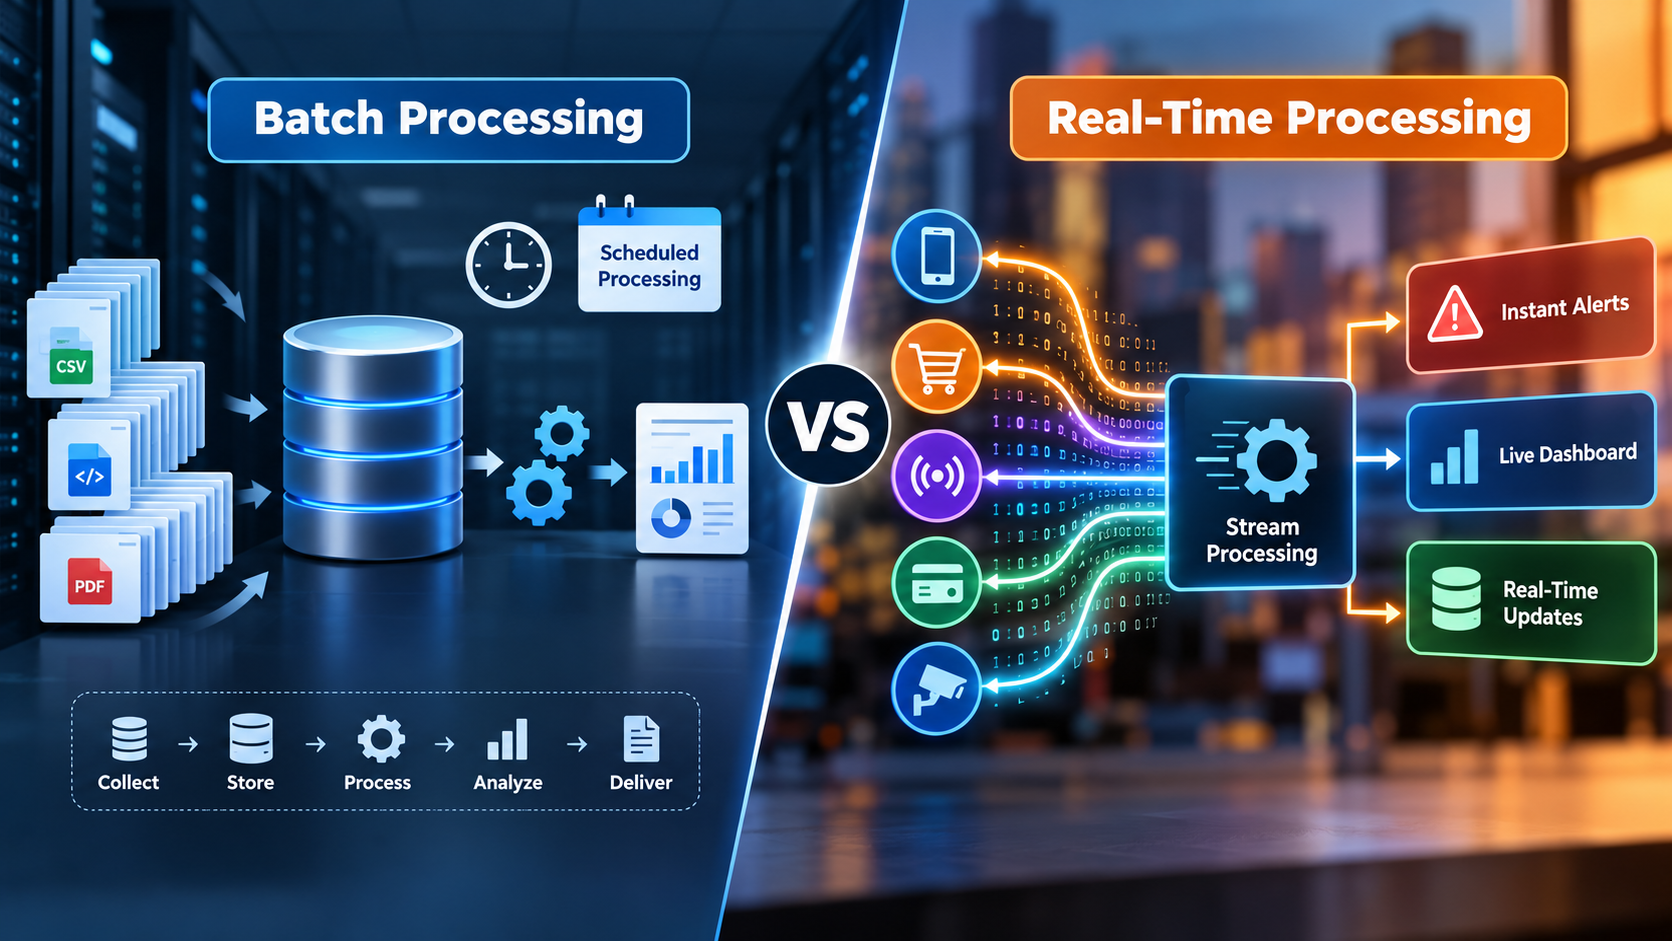
Data Mesh vs Data Fabric is a choice between two ways of managing data at scale. Gartner describes data fabric as a design concept that connects data across systems through metadata and automation. It describes data mesh as an architectural approach that gives business-focused teams responsibility for their own data products. Gartner frames data fabric as data management and data mesh as data architecture, as explained in its guide to defining a data fabric.
Picking the wrong model costs time and budget, so this guide explains what each one does, where it fits, and how to decide. A data fabric builds on the metadata and infrastructure a company already has rather than replacing it, according to Gartner’s analysis of data fabric architecture. This guide walks through the key differences, the benefits and trade-offs, and a simple way to choose.
What Is Data Fabric?
A data fabric is a way to connect data across many sources without moving everything into one place. It sits above your existing systems, such as warehouses, lakes, and cloud apps, and uses metadata to link them together.
Gartner stresses that data fabric is a design, not one product. Teams build it from several components that work together. You won’t buy a single box labeled data fabric.
How Data Fabric Connects Data
Think of a data fabric as a map that also knows how to act. It records where data lives, who uses it, how it changes, and how it relates to other data. With that context, the system can handle routine tasks, such as profiling a new dataset or matching a new source’s columns to an existing schema.
This matters most for organizations with many legacy systems. Each new integration usually means custom code and ongoing maintenance. A data fabric reduces that work by letting automation handle more of the repetitive steps.
Active Metadata and Knowledge Graphs
Gartner separates metadata into passive and active types. Passive metadata includes things like schemas, glossaries, and logs. Active metadata is the kind a system analyzes continuously to spot patterns and suggest or make changes.
Knowledge graphs add meaning to that metadata. They show how a customer record, an invoice, and a support ticket relate to each other across systems. In a data fabric, the graph helps the system find connections that a human would otherwise have to document by hand.
What Is Data Mesh?
A data mesh is an organizational approach to managing analytical data. Instead of one central data team that owns every pipeline and dataset, business domains own the data they produce. Marketing owns marketing data. Finance owns financial data. Each domain then serves that data to the rest of the company.
Dehghani laid out the idea in detail in her 2022 book, Data Mesh: Delivering Data-Driven Value at Scale. She framed it as a sociotechnical approach. That means it changes how people work, not only which tools they use.
The Four Principles of Data Mesh
Data mesh rests on four principles that work together:
- Domain-oriented ownership: Business teams own and manage the data they generate.
- Data as a product: Each domain treats its data like a product, with clear quality standards, documentation, and users in mind.
- Self-serve data platform: A shared platform gives domain teams storage, compute, and pipeline tools without rebuilding the basics each time.
- Federated computational governance: Domain representatives agree on global rules, and automation enforces them.
Each principle supports the others. Domain ownership fails without a platform that lowers the effort of running data products. Data products fail without shared governance that keeps them consistent.
What a Data Product Looks Like
A data product is more than a table. It has an owner, a defined purpose, service levels, and documentation. Consumers can find it in a catalog and trust its quality. If the product changes, the owner communicates the change, much as a software team would release a new version of an app.
Data Mesh vs Data Fabric: Key Differences
The two approaches differ in five main areas. Understanding them helps you see why one may fit your company better than the other.
Ownership and Accountability
Data mesh moves ownership to the teams closest to the data. Accountability follows that ownership. If a sales dataset is wrong, the sales domain fixes it.
Data fabric keeps ownership more centralized in a data management function. The fabric automates integration and quality checks, but a central team typically designs and runs it.
Architecture
Data mesh is an architecture of decentralized domains that publish data products to one another. Each domain can choose its own tools within the shared platform rules.
Data fabric is an architecture of connected layers. Metadata and automation link the sources, and the fabric presents a unified view of the data to users.
Governance
Data mesh uses federated governance. Domains agree on standards and enforce them locally.
Data fabric governance is driven by metadata and policy. Rules attach to the data itself, and the system applies them across connected sources.
Technology Dependence
Gartner notes that data fabric relies heavily on existing tools and platforms. Its strength comes from connecting what you already have.
Data mesh depends more on organizational change. You can build it with many tools, but it doesn’t work without clear ownership, product thinking, and skilled domain teams.
Level of Automation
A data fabric aims to automate integration, discovery, and parts of data management using active metadata and machine learning. Automation is central to the design.
Data mesh automates the platform and governance checks, but its main value comes from people owning and improving their data. Automation supports the model rather than defining it.
Data Mesh vs Data Fabric Comparison Table
| Factor | Data Fabric | Data Mesh |
| Core idea | Connected layer of data and processes | Decentralized ownership by business domains |
| Main focus | Integration, discovery, and automation | Accountability, data products, and scale |
| Primary driver | Metadata and active metadata | Organizational structure and product thinking |
| Ownership | Usually central data management | Business domains own their data |
| Governance | Policy applied through metadata | Federated rules enforced by domains and automation |
| Technology | Works with existing tools and platforms | Built on a shared self-serve platform |
| Change required | Mostly technical | Mostly organizational and cultural |
| Best fit | Many legacy systems and heavy integration needs | Large organizations with many data-producing teams |
| Main risk | Complexity and dependence on metadata quality | Weak ownership and uneven skills across domains |
Benefits of Data Fabric
A data fabric helps most when integration consumes too much time and budget. Several benefits follow from that design.
Faster Integration Across Systems
Automated profiling and schema matching cut the time needed to connect new sources. Teams spend less effort writing and maintaining custom pipelines.
Unified Visibility Through Metadata
Because the fabric tracks metadata across systems, users can see where data comes from and how it moves. Lineage and context become easier to follow.
Lower Friction for Central Data Teams
Central teams often become bottlenecks. Automation lets them support more requests without adding headcount for every new source.
Reuse of Existing Investments
A data fabric works alongside existing warehouses and lakes. You add metadata and automation rather than rebuilding everything.
Benefits of Data Mesh
A data mesh suits organizations where the central team can’t keep up with demand. Its main strengths come from ownership and speed.
Faster Access for Business Teams
When domains own their data, they can publish and change data products without waiting in a central queue.
Scalability as the Organization Grows
Each new domain adds its own data products rather than adding load to one team. The model scales with the number of data producers.
Clear Accountability for Quality
When the team that creates data also answers for its quality, problems get fixed closer to their source. Consumers know who to contact.
Limitations and Trade-offs
Neither approach is free. Each brings costs that teams often underestimate.
Common Data Fabric Pitfalls
A data fabric depends on good metadata. If documentation is weak or sources are poorly described, automation produces poor results. Teams also risk building a complex system that few people understand.
Common Data Mesh Pitfalls
Data mesh requires a cultural shift. Domain teams need time, skills, and incentives to manage data well. Without them, ownership exists on paper only. Some organizations also see duplicated work across domains if the shared platform and governance are thin.
When to Use Data Fabric
A data fabric fits best when your main challenge is connecting many systems.
- Your company runs many legacy systems that are hard to integrate.
- Your central data team spends most of its time on pipeline maintenance.
- Regulated industries need consistent policy enforcement across sources.
- You already have metadata tools or a data catalog to build on.
If your teams already own their data well, a fabric may simply add a layer of automation to a process that works.
When to Use Data Mesh
A data mesh fits best when your main challenge is scale and ownership.
- Many business units produce and use data independently.
- A central data team has become a bottleneck for requests.
- Domain teams have technical skills or are willing to build them.
- Leadership supports a shift in how data responsibility is shared.
Data mesh asks more of your culture. If leadership wants to keep control centralized, the model will struggle.
Can You Use Data Fabric and Data Mesh Together?
Yes, and many organizations do. Gartner notes that a data fabric can work with different integration styles, while data mesh can guide design within a technology-agnostic framework. The two overlap in shared metadata, catalogs, and governance.
A common pattern looks like this. Domains own and publish their data products, which follows data mesh principles. A fabric-style metadata layer then connects those products, automates discovery, and enforces policy. Ownership sits with the domains, and the fabric handles connection and automation.
How to Choose: A Practical Decision Framework
Work through these steps before you commit to either approach.
Step 1: Assess Your Organizational Structure
Count the teams that produce data. If a handful of central teams handle most of it, a fabric may be enough. If dozens of business units produce data, domain ownership may fit better.
Step 2: Assess Your Data Maturity and Tooling
Check what you already have. Do you run a data catalog? Do you track lineage? Strong metadata practices make a data fabric easier to build. Weak practices suggest starting with basic catalog and governance work first.
Step 3: Estimate Cost and Time to Value
Both approaches cost money and time. Fabric projects often start with integration savings. Mesh projects often start with platform and skills investment. Build a small pilot in one domain or one integration path, then measure results before expanding.
If you need outside help assessing your data architecture, our data analytics services cover strategy, integration, and analytics work for teams at different maturity levels.
Frequently Asked Questions
Data mesh is an organizational approach that moves data ownership to business domains and treats data as a product. Data fabric is a design concept that uses metadata, automation, and knowledge graphs to connect data across systems. One focuses on who owns data. The other focuses on how data connects and gets delivered.
Data mesh is best described as a sociotechnical approach. It combines organizational change with technical patterns, including domain ownership, data products, and a shared self-serve platform. Teams build it with many different tools, so there is no single product to buy.
Not on its own. Gartner describes data fabric as a design concept rather than a single technology. Vendors sell products that support parts of the design, such as catalogs, knowledge graphs, and integration tools. Organizations usually assemble a fabric from several components, linked by metadata.
Smaller teams often start with simpler centralized data management. As the number of data producers grows, either approach may become useful. A data fabric can help if integration is the pain point. Data mesh can help if ownership and request backlogs are the pain point.
Yes. Gartner notes that data fabric can work with different integration styles, while data mesh can guide design within a technology-agnostic framework. Many organizations use a fabric-style metadata layer to connect domain-owned data products, which combines automation with clear ownership.
Both approaches rely heavily on metadata, so a catalog helps in each case. In a data fabric, the catalog often forms the starting point. In a data mesh, teams register product ownership and documentation there so other domains can find and trust the products.
Federated governance means representatives from each domain agree on global standards. These cover things like data product interfaces, schemas, identifiers, security policy, and quality metrics. Each domain then applies the rules to its own products, and automation helps enforce them consistently.
Teams need product thinking, domain knowledge, and software engineering skills to publish reliable data products. Platform engineering skills are also important for the self-serve infrastructure. Leaders must support clear ownership, and data producers must understand the quality standards their consumers expect.
No. Gartner explains that a data fabric does not require a rip and replace approach. It works with existing warehouses, lakes, and logical data warehouses, adding metadata and automation on top. The fabric connects these systems so people can find and use data more easily.
Start with your structure and your main pain points. If a central team can’t keep up with requests from many business units, data mesh principles may help. If your systems are scattered and integration consumes most of your effort, a data fabric may fit better. Assess skills, tooling, and budget before you commit.
Conclusion
When you weigh Data Mesh vs Data Fabric, you weigh two different solutions to two different problems. A data fabric connects systems through metadata, automation, and knowledge graphs, which helps when integration eats up your team’s time. A data mesh moves ownership to business domains that treat their data as products, supported by a self-serve platform and federated governance, which helps when one central team becomes the bottleneck. Both models bring trade-offs. A fabric depends on strong metadata, and a mesh depends on skills and clear ownership in every domain.
Many organizations combine the two, letting domains own their data products while a metadata layer handles discovery and policy. Start by identifying the problem you feel most. Then run a small pilot in one domain or one integration path, and measure the time saved or the backlog cleared before you expand. For help planning that pilot, explore our data analytics services.