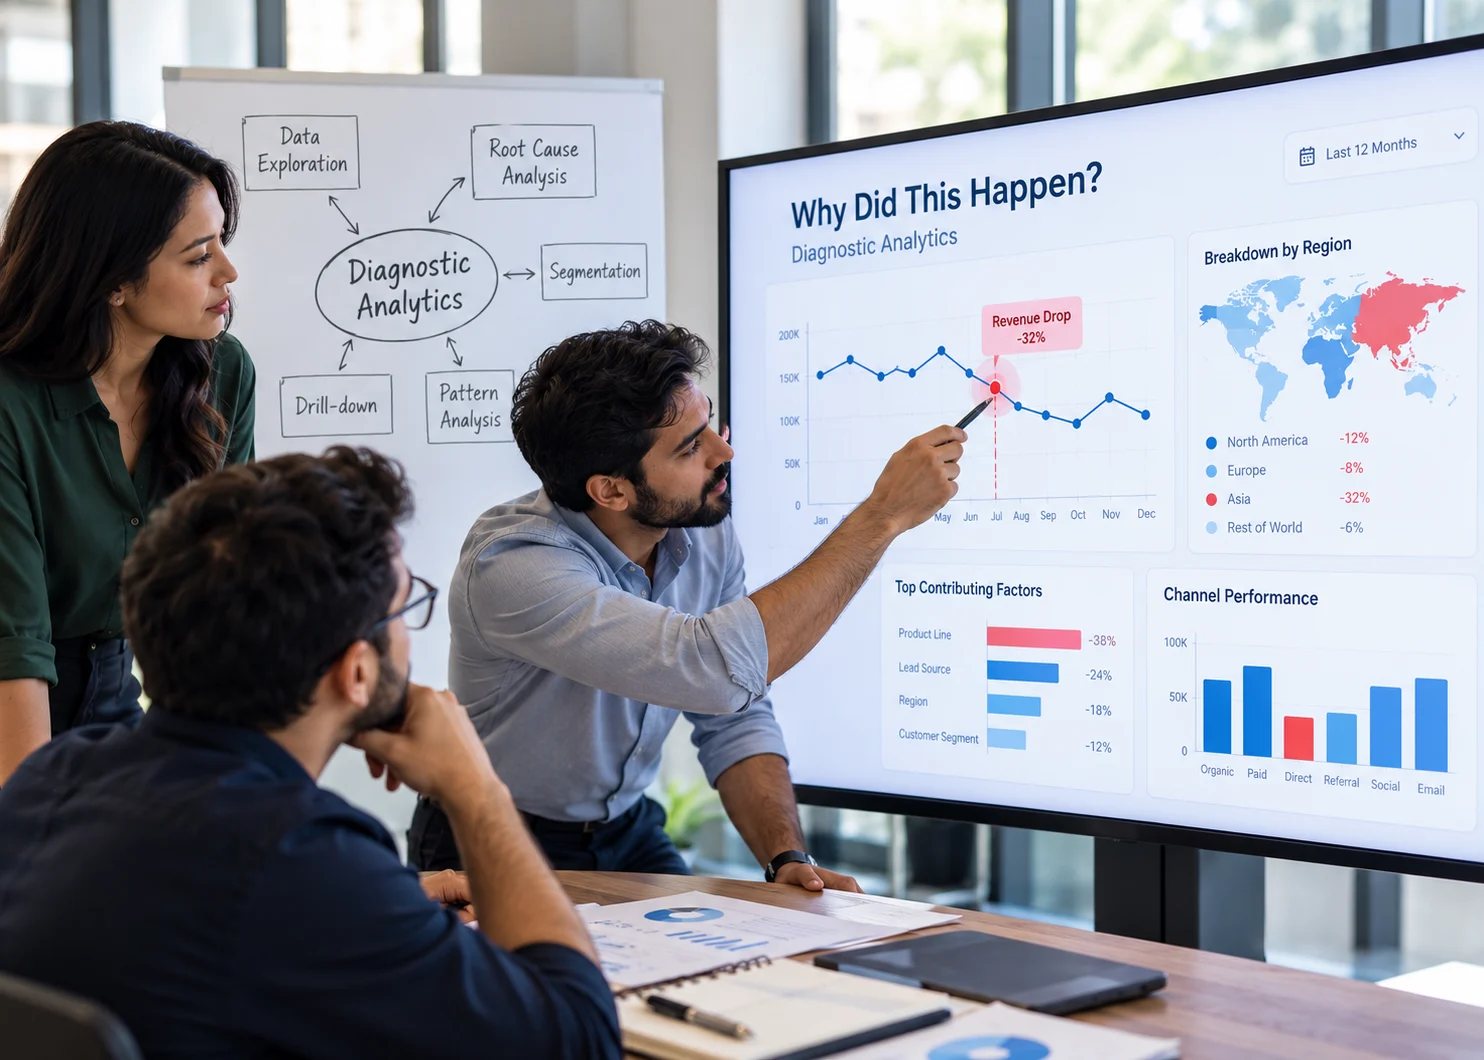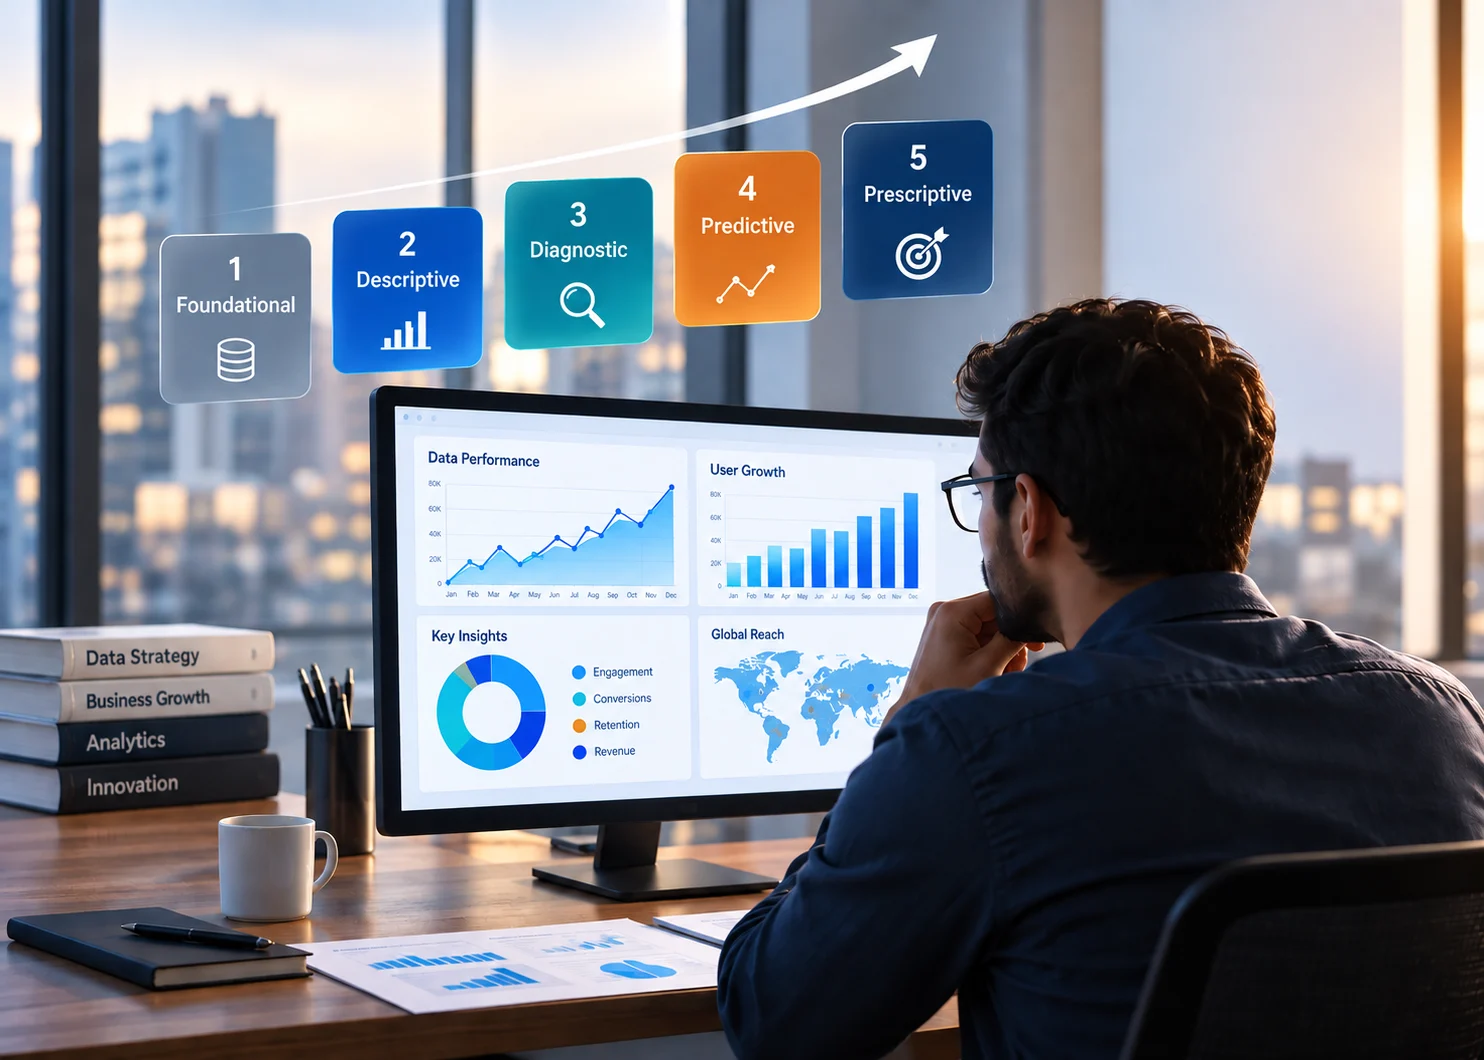
Gartner research from 2020 puts the cost of poor data quality at $12.9 million a year for the average organization. Gartner dates that figure to 2020, so use it as a rough benchmark, not a forecast for your own business. The pattern behind it holds up: bad records quietly break dashboards, forecasts, and AI projects.
Data quality management fixes that problem on purpose instead of by accident. This guide covers what data quality means, the key metrics to monitor, who is responsible for each task, and how to implement a practical five-phase data quality roadmap.
What Is Data Quality Management?
Data quality management is the set of practices, roles, and rules an organization uses to keep data fit for the way people use it. It covers finding data problems, fixing them, and stopping them from coming back.
Gartner describes data quality as how usable and applicable data is for an organization’s priority use cases, including AI and machine learning. The word “priority” matters. You do not need perfect data everywhere. You need dependable data where decisions and revenue depend on it.
Data Quality vs. Data Quality Management
- Data quality is a state: how good your data is right now.
- Data quality management is the ongoing work that measures that state, improves it, and protects it.
How It Connects to Related Disciplines
- Data governance sets policies, standards, and decision rights. Gartner notes that data quality is usually one of the goals of effective data management and governance.
- Master data management keeps one trusted version of core records such as customers and products.
- Data observability watches pipelines and tables for breaks, delays, and unusual changes.
- Data quality management sits across all three and checks whether the data meets the bar.
The Core Activities
- Data profiling: measure what your data looks like today
- Data cleansing: fix errors, remove duplicates, and standardize formats
- Data validation: block bad values before they enter your systems
- Monitoring: track data quality metrics over time
- Root cause analysis: find why issues appear, not only where
- Metadata and data lineage: document what data means and where it came from
Why Data Quality Management Matters for Analytics and AI
Poor data hurts in four places.
Decisions and Forecasts
A dashboard built on duplicate or stale records gives confident answers that are wrong. Forecasting models inherit every flaw in their inputs. If you want to see how analytics supports better choices, read how predictive analytics improves decision-making in enterprises.
AI Readiness
Gartner predicts that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data. Gartner also states that if data has issues, it is not ready for AI. Our guide on the role of AI in modern data analytics shows why clean inputs matter before any model goes live.
The Measurement Gap
Gartner surveys found that 59% of organizations do not measure data quality. Without a number, nobody can say what bad data costs or whether a fix worked.
Compliance and Trust
Gartner lists growing regulation, including GDPR and CCPA, as a common challenge. Accurate records make it easier to answer access, correction, and deletion requests.
The Core Data Quality Dimensions
Data quality dimensions are the lenses you use to judge data. Gartner lists nine common ones: accessibility, accuracy, completeness, consistency, precision, relevancy, timeliness, uniqueness, and validity.
Most teams start with six:
- Accuracy: values match real-world facts
- Completeness: required fields and records are present
- Consistency: the same fact looks the same across systems
- Validity: values follow business rules and formats
- Timeliness: data arrives and updates fast enough to be useful
- Uniqueness: each real-world entity appears once
Gartner advises against applying every dimension to every dataset. Pick the ones that matter for each use case, then measure two or three of them well.
Data Quality Metrics to Track
A dimension tells you what to care about. A metric turns it into a number you can track.
The examples below are illustrative. They show how each formula works and are not industry benchmarks.
| Dimension | Metric | Formula | Illustrative example |
| Completeness | Completeness rate | Filled required values ÷ total required values × 100 | 9,200 of 10,000 leads have a phone number = 92% |
| Uniqueness | Duplicate rate | Duplicate records ÷ total records × 100 | 400 duplicates in 10,000 contacts = 4% |
| Validity | Validity rate | Records passing format and business rules ÷ records checked × 100 | 9,600 of 10,000 emails pass format checks = 96% |
| Accuracy | Match rate to a trusted source | Records matching the source ÷ records sampled × 100 | 880 of 1,000 sampled addresses match = 88% |
| Consistency | Cross-system match rate | Matching values across systems ÷ records compared × 100 | 9,000 of 10,000 customer statuses agree = 90% |
| Timeliness | Freshness | Records updated within the agreed window ÷ total records × 100 | 8,000 of 10,000 records updated on time = 80% |
Operational Metrics
Field-level numbers show the state of your data. These show how well your program runs:
- Number of open data quality issues
- Time to detect an issue
- Time to resolve an issue
- Share of critical data elements covered by automated rules
- Share of rules passing each day
Build a Simple Data Quality Score
A data quality score combines multiple metrics into a single figure that leaders can monitor. Weight each metric by business impact. For example, with completeness at 30%, uniqueness at 25%, validity at 25%, and timeliness at 20%, scores of 92, 96, 88, and 80 give a weighted score of 89.4.
Treat that weighting as a starting point. Agree on the weights with the business owners who use the data.
Set Targets by Business Impact
No single threshold fits every dataset. Gartner recommends working with stakeholders to define the metrics and expected quality levels, then selecting two or three priority metrics per use case. Gartner also suggests plotting profiling results on a heat map to see where problems sit and which ones matter most.
A scorecard works best when everyone can read it at a glance. Dashboards from data visualization services can turn these metrics into a live view that owners check weekly.
Data Quality Management Roles and Responsibilities
Technology rarely fails first. Ownership does. Gartner reports that business leaders agree with data quality matters, but many do not see it as their job. Gartner calls data quality a business discipline, because the way people enter, use, and manage data decides the outcome.
Titles vary by company. The jobs matter more than the names.
| Role | What they own | Question they answer |
| Executive sponsor | Budget, priorities, escalation | Is this worth funding? |
| Data owner | Standards and accountability for one data domain | What does good look like here? |
| Data steward | Daily monitoring, issue triage, fixes | Who fixes this record? |
| Data quality lead | The program, scorecard, and roadmap | Are we improving? |
| Data engineer | Automated checks, pipelines, alerts | Can we catch this at the source? |
| Data analyst | Profiling, metric reporting, root cause analysis | Where does the problem start? |
| Business users | Accurate data entry and issue reporting | Did I capture this correctly? |
What a Small Team Can Do
You do not need seven people. With three, assign one business leader as data owner, let an analyst act as data steward, and have an engineer build the automated checks. If capacity is the bottleneck, you can hire a data analyst to take on profiling and stewardship work.
A Practical Data Quality Management Roadmap
This data quality roadmap has five phases. The timeframes are planning guides, not benchmarks. Adjust them to your team size and data volume.
Phase 1: Scope and Baseline (Weeks 1 to 4)
- Map your business use cases by value and risk, as Gartner suggests
- Choose two or three data quality metrics per use case
- Run data profiling: column-based profiling gives statistics, and rule-based profiling checks data against business logic
- Build a heat map of problem areas
Done when: a baseline scorecard exists for your highest-priority data.
Phase 2: Assign Owners and Standards (Weeks 3 to 6)
- Name a data owner and steward for each priority domain
- Write plain-language definitions for critical fields
- Set target levels with the business
- Create a simple issue log
Done when: every critical data element has an owner and a written standard.
Phase 3: Automate Checks (Weeks 6 to 12)
- Add data validation at the point of entry
- Build automated tests into your pipelines
- Set alerts for failed rules and freshness gaps
- Publish the scorecard
Done when: failed checks alert a named person within the agreed window. If you want hands-on help with the pipelines and dashboards, our data analytics services cover that kind of build.
Phase 4: Fix Root Causes
- Run root cause analysis on repeat issues
- Remove the cause, such as a missing required field or a broken integration mapping
- Clean existing records through data cleansing and deduplication
- Track whether the same issue returns
Done when: your top five recurring issues stop recurring.
Phase 5: Scale and Improve (Ongoing)
- Expand to the next data domain
- Review data quality metrics and targets each quarter
- Add checks that prove data is ready for machine learning projects
- Document metadata and data lineage for critical datasets
Done when: the program runs as a routine, not a project.
Data Quality Management Approaches Compared
Gartner highlights ten capabilities to weigh when choosing data quality tools, including profiling, cleansing, matching, rule management, monitoring, and lineage. It also notes that these tools support wider processes such as data integration and master data management.
The table compares common approaches, not specific vendors.
| Approach | Best for | Effort to start | Scale | Main limit |
| Manual spreadsheet checks | One-off cleanups and small datasets | Low | Low | Does not repeat reliably, so errors return |
| Custom SQL and pipeline rules | Teams with engineers and well-known rules | Medium | Medium to high | Needs engineering time and rule upkeep |
| Dedicated data quality platform | Shared data across many teams that needs profiling, matching, and workflows | Medium to high | High | License cost, setup effort, and change management |
| Data observability | Catching pipeline breaks, freshness gaps, and volume anomalies | Medium | High | Shows that something changed, not whether data fits a business need |
| AI-assisted (augmented) data quality | Large data estates that need suggested rules and anomaly detection | High | High | Needs good metadata and human review of suggestions |
Gartner describes augmented data quality as a shift that uses active metadata, AI, and graph technologies. Even so, choose tools only after you define owners, metrics, and priority use cases. A tool without owners just finds problems faster.
Data Quality in CRM and BI Reporting
CRM data shows the cost of poor quality fast. Sales teams work from these records daily, so errors spread quickly.
Common CRM Problems
- Duplicate leads and contacts
- Missing phone numbers, industries, or deal stages
- Inconsistent picklist values
- Stale records after job changes
Salesforce’s own training material explains that matching rules and duplicate rules work together to warn reps about potential duplicates before they save a record. It also notes limits of up to three matching rules per duplicate rule and up to five active matching rules per object. Tools like these catch duplicates at entry, which costs far less than cleaning them later.
Good CRM metrics to start with: duplicate rate on leads, completeness of key opportunity fields, and share of records updated in the last 90 days. To see how clean CRM data feeds reporting, read what is CRM analytics. If your team wants help applying these controls inside Salesforce, Salesforce CRM analytics consulting is a natural next step.
Common BI Problems
Two dashboards show different revenue because each uses a different definition. Agree on one definition per metric, document it as metadata, and publish it where report builders can see it.
Real-World Example: Improving CRM Data Quality
Consider a company that manages thousands of customer records in its CRM system. Over time, sales representatives create duplicate leads, leave important fields empty, and enter phone numbers in inconsistent formats. These issues make it difficult for the sales team to identify genuine prospects and produce reliable reports.
The company can improve its data quality management process through a few practical steps.
Identify the problems: The data analyst profiles the CRM database and discovers that 8% of customer records are duplicates, while 12% of leads are missing a phone number.
Assign ownership: The sales operations manager becomes the data owner, while a data steward monitors data quality issues and coordinates corrections.
Introduce validation rules: The technical team configures duplicate detection, requires essential fields during lead creation, and standardizes phone number formats.
Measure the results: The team tracks duplicate rates, completeness rates, and the number of unresolved data quality issues through a weekly scorecard.
For example, if the duplicate rate falls from 8% to 3% and the completeness rate improves from 88% to 97%, the company has measurable evidence of progress. These figures are illustrative, not industry benchmarks.
This example shows why effective data quality management requires more than cleaning existing records. Clear ownership, preventive validation, and continuous monitoring help organizations maintain reliable CRM data over time.
Common Data Quality Management Mistakes
- Buying tools before assigning owners. Software flags issues, but people fix them.
- Chasing 100% everywhere. Aim for fit for purpose on priority data.
- Skipping the business link. Tie every metric to a decision, a process, or a cost.
- Cleaning without fixing causes. Without root cause analysis, the same errors return.
- Measuring once. A baseline helps, but trend lines prove progress.
- Ignoring data entry. Better forms and required fields often beat later cleanup.
Frequently Asked Questions
Data quality management is the ongoing practice of keeping data accurate, complete, consistent, and fit for its intended use. It combines rules, tools, and clear ownership. Teams profile their data, fix errors, validate new records, and monitor results with metrics. The goal is dependable data for analytics, reporting, and AI, not perfect data everywhere.
The most common data quality dimensions are accuracy, completeness, consistency, validity, timeliness, and uniqueness. Gartner lists nine in total, adding accessibility, precision, and relevancy. You do not need all of them. Pick the two or three that matter most for each use case, then define a metric for each one.
Start with completeness rate, duplicate rate, validity rate, accuracy against a trusted source, and data freshness. Add operational data quality metrics such as open issues, time to detect, and time to resolve. The right mix depends on the business use case, so tie every metric to a decision or process that suffers when the number drops.
Choose the dimensions that matter, define a formula for each, and run data profiling against a sample or the full dataset. For example, divide filled required fields by total required fields to get a completeness rate. Track results on a scorecard over time, and set targets by business impact rather than one universal number.
Business teams own data quality because they create and use the data. A data owner sets standards for each domain, and data stewards handle daily checks and fixes. Data engineers build the automated controls. An executive sponsor funds the work and settles disputes. Gartner stresses that data quality is a business discipline, not only an IT task.
Data governance sets the policies, standards, and decision rights for how an organization handles data. Data quality management applies those standards day to day by measuring data, fixing issues, and monitoring results. Governance decides what good looks like and who is accountable. Quality management checks whether the data meets that bar and acts when it does not.
Work in five phases. First, scope critical use cases and baseline their data. Second, assign owners and standards. Third, automate validation and alerts. Fourth, fix root causes, not just symptoms. Fifth, scale to new data domains and review metrics quarterly. Give each phase a clear finish line so progress stays visible to leadership.
No universal score exists. A good score meets the needs of the specific use case. A marketing email list may need, for example, 98% valid addresses, while an internal analysis can tolerate more gaps. Set targets with business stakeholders, weight metrics by impact, and judge progress by trend. Gartner advises limiting each use case to two or three priority metrics.
Poor data quality produces misleading dashboards, weak forecasts, and unreliable AI outputs. Gartner predicts that through 2026, organizations will abandon 60% of AI projects not supported by AI-ready data. Duplicates, gaps, and stale records feed models the wrong patterns and erode trust in every report and decision built on them.
Teams use spreadsheets and SQL checks for small jobs, then move to dedicated data quality tools, data observability platforms, and AI-assisted solutions as volume grows. Gartner lists profiling, cleansing, matching, rule management, monitoring, and lineage among critical capabilities. Choose tools only after you define owners, metrics, and priority use cases.
Conclusion
Data quality management is not a one-time cleanup. It is a habit that keeps your reports, forecasts, and AI projects running on data your team can trust. The approach rests on three ideas: measure what matters by choosing the data quality dimensions that fit each use case and turning them into data quality metrics, give every priority dataset a named owner and data steward, and follow the roadmap in order, from baseline to standards, automation, root cause fixes, and scale.
You do not need a big budget or a new platform to begin. This week, pick one high-value dataset, such as your CRM leads or customer records. Run data profiling, calculate two or three metrics, and name the person who owns the result. Then share the first scorecard with the people who rely on that data.
Progress will look small at first, but a lower duplicate rate or a higher completeness rate is real evidence, and each win makes the next dataset easier to fix. Teams that build this discipline now will have cleaner inputs when their analytics and AI demands grow.